Explorar las categorías
Explora
Fiverr Pro
Español
$
USD
Data Engineer Data Architect Azure Databricks Microsoft Fabric
Habilidades
Revisa mis servicios

Senior Data Engineer
KGroup Global Services • Tiempo completo
May 2026 - Sep 2026 • 4 mos
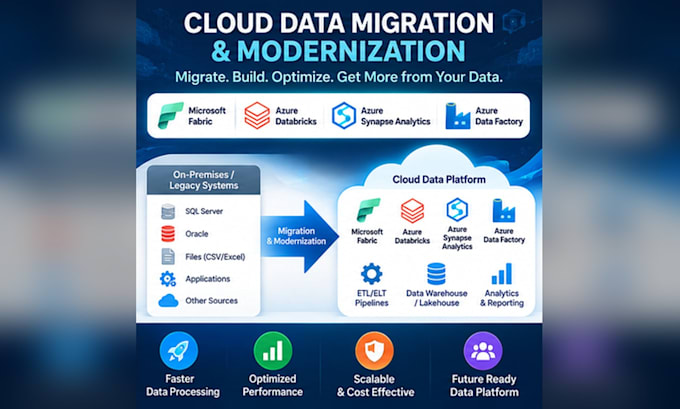
• Design Lakehouse architecture based on Medallion architecture on MS Fabric • Migrate legacy system to Lakehouse architecture • Designed and implemented automation workflows and Azure services including Azure Data Factory and data bricks on Fabric • Monitor data pipelines, troubleshoot issues and implement optimization for performance and reliability. • Built and monitored interactive dashboards and reporting solutions using Power BI, integrating with Fabric and Databricks for real-time data insights as part of the data engineering ecosystem. • Automated business processes and optimized database integration using Python, Apache Spark, Databricks, and cloud-based ETL pipelines. Delivered scalable analytics solutions across hybrid environments, supporting advanced data modeling and performance tuning. • Manage and Lead team to meet SLA and work flows. • Monitor and support job failure for different jobs running across different platform like Talend, Databricks, Fabric, SSIS, ADF.

Technical Lead
Coforge • Tiempo completo
Jul 2025 - May 2026 • 10 mos
• Develop, test, and deploy data ingestion, transformation and processing using Azure services • like Azure Data Factory, Azure Data Lake Storage, Talend, Microsoft Fabric based on medallion architecture • Designed and implemented automation workflows and Azure services including Azure Data Factory and Fabric Powe BI • Monitor data pipelines, troubleshoot issues and implement optimization for performance and reliability. • Built and monitored interactive dashboards and reporting solutions using Power BI, integrating with Azure and Databricks for real-time data insights as part of the data engineering ecosystem. • Automated business processes and optimized database integration using Python, Apache Spark, Databricks, and cloud-based ETL pipelines. Delivered scalable analytics solutions across hybrid environments, supporting advanced data modeling and performance tuning. • Manage and Lead team to meet SLA and work flows. • Monitor and support job failure for different jobs running across different platform like Talend, Databricks, Fabric, SSIS, ADF.

Senior Data Engineer
Resurgent Enterprise Solutions • Tiempo completo
Dec 2023 - May 2025 • 1 yr 5 mos
• Develop, test, and deploy data ingestion, transformation and processing using Azure services • like Azure Data Factory, Azure Data Lake Storage, Microsoft Fabric • Designed and implemented medallion architecture ,automation workflows and Azure services including Azure Data Factory • Monitor data pipelines, troubleshoot issues and implement optimization for performance and reliability. • Built and monitored interactive dashboards and reporting solutions using Power BI, integrating with Azure and Databricks for real-time data insights as part of the data engineering ecosystem. • Automated business processes and optimized database integration using Python, Apache Spark, Databricks, and cloud-based ETL pipelines. Delivered scalable analytics solutions across hybrid environments, supporting advanced data modeling and performance tuning. • Data transformation using PySpark and python for ETL/ELT pipeline. • Develop CI/CD along with SCD I/II with GitHub action for streaming data.
