Explorar las categorías
Explora
Fiverr Pro
Español
$
USD
Business data extraction and spreadsheet cleanup, with sources on every row
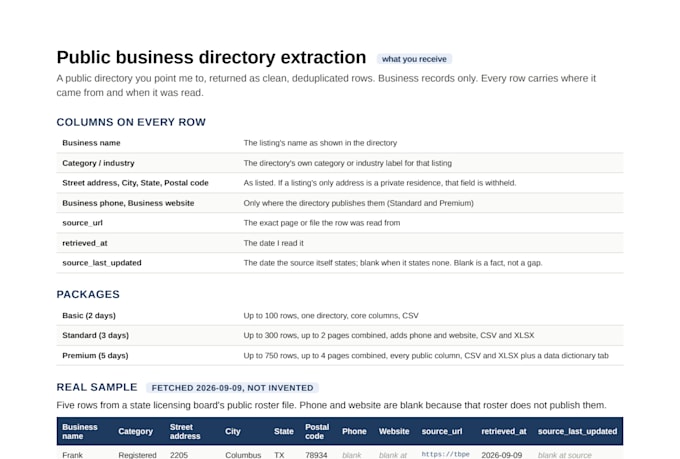
You have a public online business directory (a chamber of commerce member list, an industry association directory, a licensing board roster, a trade group member page) and need it as a spreadsheet instead of a page. I read a public directory you point me to and return the listings as clean, deduplicated rows for outreach, market research, or a CRM import.
Scope: only directories publicly accessible without a login, allowed under robots.txt and terms for automated reading. A locked, paywalled, or terms-restricted source is declined before work starts, at no charge.
Only business-level facts are collected: name, category, address, and public contact details where listed. No personal data about private individuals.
Every row carries three provenance columns: source_url (the exact page or file the row came from), retrieved_at (the date I read it), and source_last_updated (the date the source itself states, blank when it states none; blank is a fact, not the same as retrieved_at).
CSV at every tier, XLSX added at Standard and Premium. Extraction is automated, with my review before delivery. The sample image in the gallery shows real, fetched rows, not invented ones.


Tecnología:
Python
•
Excel
•
Beautiful Soup
•
Pandas
Tipo de información:
Listas
•
Sitios web
Técnica:
Automatizado
What if the directory is login-walled, blocked by robots.txt, or its terms forbid extraction?
I decline before any work starts and you are not charged. Every order is extracted fresh from the source you name; nothing is a premade list.
Is the extraction automated?
Yes. Extraction runs automatically, and I review the output before delivery.
How accurate is the data, and do you correct errors in the directory?
Accuracy is as shown at the source on the retrieved_at date. I don't correct or verify the directory's own data; if the directory has it wrong, the row reflects what the directory says.
Do you collect personal data about individuals?
No. This is business-level data only: business name, category, address, and public contact details where the directory lists them. If a listing's only address is a private residence, that field is withheld.