Explorar las categorías
Español
$
USD
Conecta tu IA a Fiverr
Azure Databricks and Microsoft Fabric Data Engineer
Habilidades
Revisa mis servicios
Technical Lead
Trianz • Tiempo completo
Jul 2026 - Present • 4 mos
Lead Databricks data engineering delivery for a US real-estate investment client. Unified properties, leases and deals across 5+ source systems into one master ID per record. Built a Databricks lakehouse using PySpark and Delta Lake. Designed config-driven Databricks jobs and guided the team on pipeline design and code quality.
Senior Data Engineer
DecisionTree Analytics • Tiempo completo
Oct 2025 - Jun 2026 • 8 mos
Designed a metadata-driven ingestion framework in Microsoft Fabric for dynamic pipeline execution. Developed Snowflake stored procedures for metadata tracking using SCD logic. Automated metadata ingestion using information_schema, cutting onboarding effort by 70%. Built parameterized pipelines for multi-environment deployment.

Data Engineer
WNS Global Services • Tiempo completo
Apr 2023 - Sep 2025 • 2 yrs 5 mos
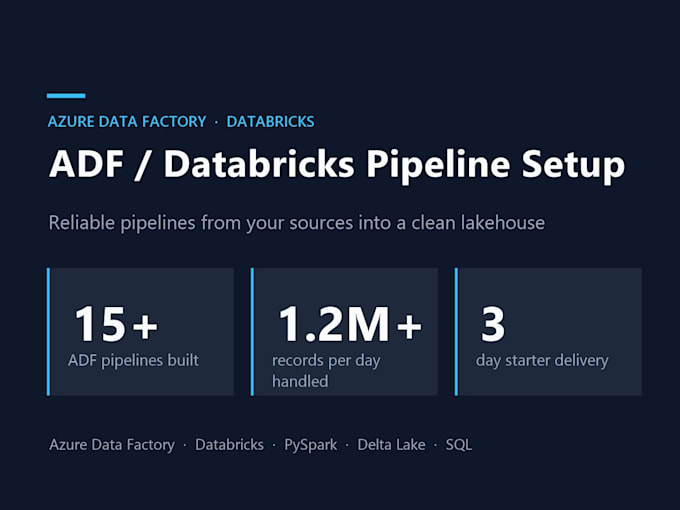
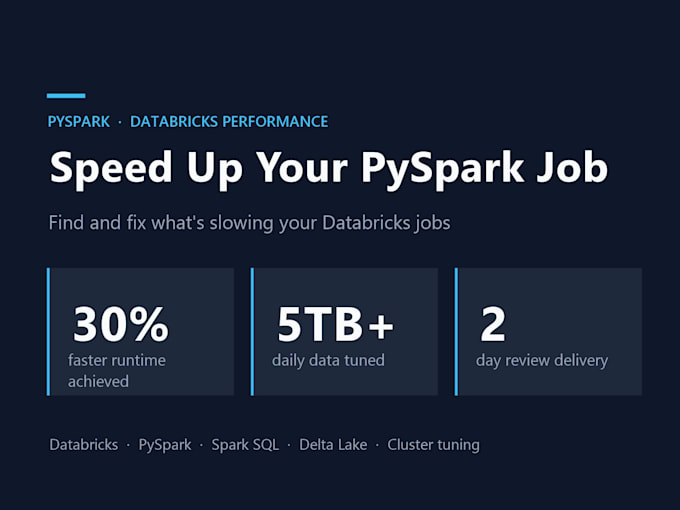
Built scalable Spark jobs in Databricks processing 5TB+ of data daily, reducing runtime by 30%. Developed 15+ Azure Data Factory pipelines handling 1.2M+ records per day. Created a PySpark validation framework maintaining 99.8% accuracy and optimized SQL queries to improve reporting performance by 56%.
